AI Product Recommendations: Audit Beyond the API
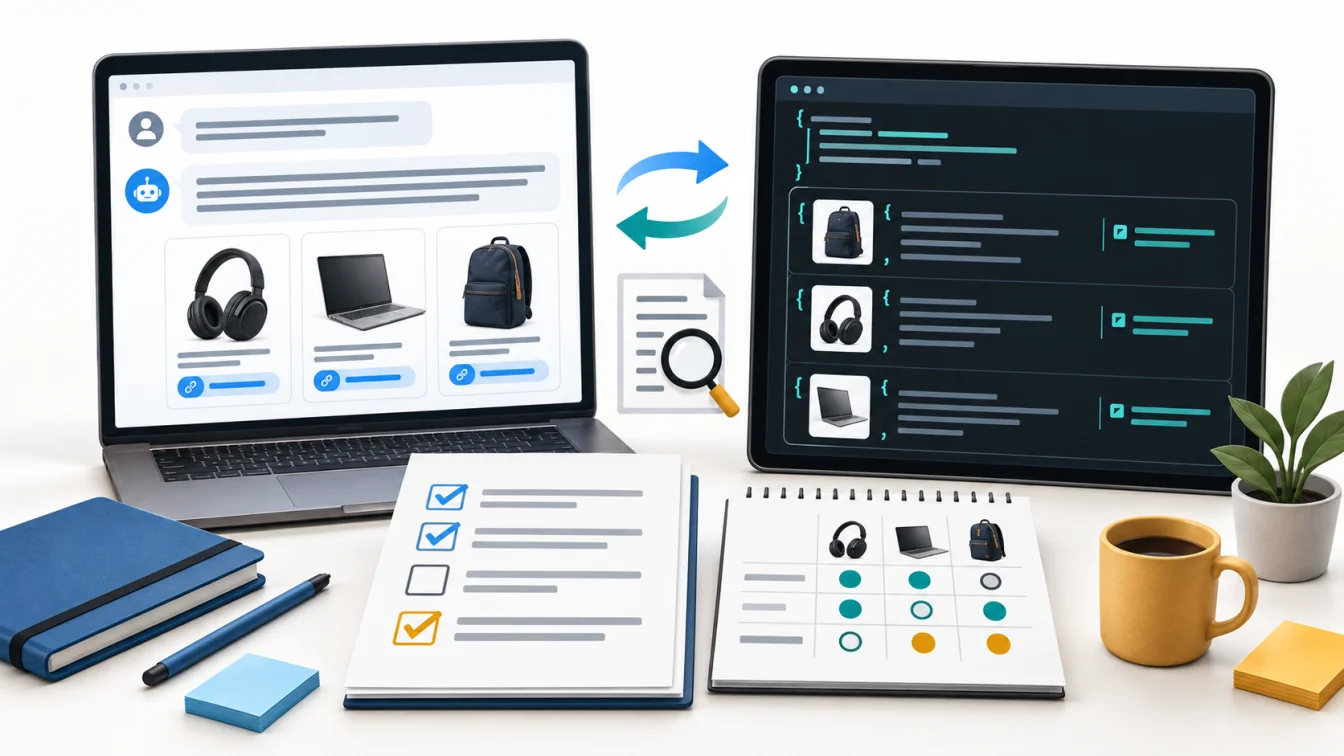
An AI product recommendation audit records which products an assistant recommends, which claims it makes, and which sources it displays under documented conditions. Test consumer interfaces and APIs separately, repeat important questions, and verify commercial facts against your catalog. A mention is not a citation, a visit, or a sale.
What does the September 2026 research actually show?
A preprint submitted on September 16, 2026 examines commercial advice across ChatGPT, Gemini, their APIs, and Google AI Overviews. Its analysis covers 1,536 responses and finds differences between interface and API source selections, alongside variation across repeated requests. The authors explicitly caution against treating API observations as a substitute for consumer-facing conditions. Read the original study.
Its scope matters: the research focuses on physical-product questions, predominantly English queries, and collection from the Netherlands. It is a time-specific audit, not a universal ranking benchmark. The comparisons do not establish why the systems differ, and this preprint is not evidence that a particular SEO tactic increases sales. Methodology and limitations.
The practical response is better measurement. The workflow below is our proposed operating method for a brand or agency, not a reproduction of the experiment or a claim that GEOCARA has independently repeated it.
Step 1: Define the buying decision before choosing prompts
A useful audit starts with a customer decision that your business can help answer. Choose one product category, one market, one language, and a small set of commercially meaningful questions. Avoid a broad question such as "What are the best products?" that has no clear success condition.
For an illustrative headphone retailer, the decision might be choosing headphones for a shared office under a specified budget. Record the budget currency, necessary compatibility, and constraints such as microphone quality or replacement parts. These are test inputs, not claims about search volume.
Build a prompt set with distinct intentions:
| Intent | Illustrative question | Evidence to inspect |
|---|---|---|
| Category discovery | Which headphones suit calls in a shared office? | Recommended products and stated reasons |
| Constraint matching | Which options work with my laptop and fit this budget? | Compatibility, price, and currency |
| Comparison | How do product A and product B differ for calls? | Specific trade-offs and supporting sources |
| Risk reduction | What should I check before buying product A? | Limitations, returns, and support |
| Ownership | Can I replace the battery or ear cushions? | Maintenance instructions and availability |
Include branded and unbranded questions, but report them separately. A prompt that names your product is easier to appear in than a discovery question. Combining both can create a flattering number that says little about acquisition.
Step 2: Keep each observation condition identifiable
An observation needs enough context for another person to understand what was tested. Use a simple shared worksheet before investing in a complex dashboard. One row should represent one prompt, one condition, and one response, not an entire campaign.
Record the following fields:
- Exact prompt and a stable prompt identifier.
- Platform, interface or API, and visible model name when available.
- Timestamp with time zone, language, and market being tested.
- Signed-in or signed-out state, without storing session credentials.
- Whether this was a fresh conversation or a follow-up.
- Search or browsing configuration when explicitly known.
- Response status, recommended products, and displayed source URLs.
- Evidence reference, such as an approved screenshot or stored response.
Mark unknown settings as unknown. Do not infer the hidden model behind an interface from the model available through an API. Use authorized access methods and respect platform conditions; an audit does not require bypassing access controls or collecting private conversations.
Where possible, compare conditions close together in time. Record catalog changes and major platform changes as annotations. Otherwise a price update between observations may look like a disagreement caused by the access method.
Step 3: Repeat a small, stable test before expanding it
Begin with a manageable pilot, for example ten prompts repeated three times under each selected condition. These are practical starting parameters, not a statistically validated minimum. Keep the prompt set unchanged during the pilot so the results remain interpretable.
Schedule observations across a documented interval instead of rerunning until a favorable answer appears. Preserve failures, missing AI answers, and unsuccessful captures. A failed request is unavailable evidence, not proof that the product was absent from a successful answer.
When the pilot exposes inconsistent results, increase the sample before making strong claims. Review the prompts that vary most and ask whether their wording hides multiple different buying decisions. Split genuinely different intentions in the next version, while preserving the earlier version for comparison.
For ongoing reporting, follow the same discipline used in brand mention tracking: fixed definitions, recorded conditions, and visible coverage. More observations help only when their meaning remains consistent.
Step 4: Separate recommendations, mentions, and evidence
Create explicit labels before scoring the answers. A product may be named only to explain why it is unsuitable. That should not count as a positive recommendation. Similarly, a brand can be recommended without a link to its website.
Use separate fields for:
- Mention: the brand or product appears in the answer.
- Recommendation: the answer presents it as suitable for the stated need.
- Visible citation: the answer displays a supporting link.
- Retrieved material: a tool response exposes a source that is not necessarily cited.
- Commercial accuracy: the answer's relevant facts match a dated authoritative record.
Do not describe every retrieved URL as a visible endorsement. Keep first-party product pages, retailers, editorial reviews, and discussion sources in separate categories. A marketplace URL can represent a seller rather than the manufacturer, so domain matching alone may misclassify ownership.
For product identity, normalize genuine variants carefully. Similar names may refer to different generations, sizes, or regional versions. Maintain a reviewed alias list and preserve the original wording so a normalization error can be corrected later.
This distinction complements the broader readiness checker versus mention tracking guide. Website quality and observed recommendations answer different questions.
Step 5: Calculate metrics with visible denominators
Start with counts, then calculate rates. For each platform and condition, display scheduled observations, usable responses, and missing observations. A comparison based on different coverage should never appear to be an equal-size experiment.
Suggested operating metrics include:
- Mention rate: usable responses mentioning the product divided by usable responses.
- Recommendation rate: usable responses recommending it divided by usable responses.
- First-party citation rate: usable responses linking to the brand's domain divided by usable responses.
- Factual error rate: checked factual claims found incorrect divided by checked factual claims.
For example, a product mentioned in eight of twenty usable responses has a 40% observed mention rate in that sample. That is an illustrative calculation, not a GEOCARA result or a market-share estimate. If five scheduled observations failed, also report twenty usable responses out of twenty-five scheduled.
Keep claim-level accuracy separate from response-level visibility. Ten wrong specifications in one answer are not ten failed responses. Do not report tiny changes as a trend without inspecting sample size, missing coverage, and repeated observations of the same prompt.
Step 6: Turn evidence into factual website fixes
Prioritize incorrect facts that could mislead a buyer before chasing a higher visibility score. Build an issue queue with the observed claim, correct fact, authoritative URL, affected prompt, responsible owner, and verification date.
A practical sequence is to reconcile product identity and specifications, then price and availability, then shipping and returns, then comparisons and use-case explanations. Improve the relevant canonical page instead of generating many near-identical pages for slight prompt variations.
Google supports product information through on-page structured data, Merchant Center feeds, or both. These mechanisms can help it understand product information and eligibility for supported experiences; they do not guarantee an AI recommendation. Use the official product data guidance and keep the visible page, markup, and feed consistent.
For Google AI features, pages must meet Search eligibility requirements; there is no special AI schema requirement or guaranteed inclusion. Check crawlability and snippet eligibility before treating absence as a content-quality verdict. Google Search Central guidance.
Run the free AI visibility checker as a readiness diagnostic, then inspect the actual pages behind the findings. It is not a substitute for the observation worksheet. Our GEO e-commerce guide provides complementary product-page context, while the GEO hub explains the broader optimization program.
Step 7: Connect observations to visits without inventing attribution
Maintain a separate acquisition view containing identifiable referral sessions, landing pages, and business events such as a qualified inquiry or purchase. Never treat the number of audit prompts as human traffic. Your own tests belong in an internal-traffic exclusion wherever the analytics setup supports it.
Use documented referral rules and retain an unknown category. A user can encounter an AI answer and later arrive directly; without additional evidence, that visit cannot be confidently assigned to the answer. Likewise, a visible citation does not prove a click occurred.
The ChatGPT referral measurement guide covers the analytics layer. Evaluate whether cited landing pages help the visitor complete the next step, rather than optimizing only for the number of appearances.
FAQ
Can an API audit tell me exactly what shoppers see?
Treat it as evidence about the tested API configuration. To evaluate a consumer experience, observe that interface separately under documented conditions. Do not label one as the other, and do not merge their results into an unexplained score.
How many prompts should a small brand start with?
Start with a bounded set of important buying questions that the team can review manually. Ten prompts with repeated observations can organize a pilot, but this is not a universal sample-size rule. Broader claims require broader, carefully designed coverage.
Should a negative mention count as visibility?
It can count as a mention, but should carry a separate sentiment or suitability label. A recommendation metric should reflect whether the answer actually presents the product as appropriate. Keep the raw evidence available for ambiguous cases.
Does accurate Product schema guarantee recommendations?
No. Structured data communicates product facts and can support eligibility for particular search features. It cannot guarantee which products an assistant selects. Correct inaccurate data because buyers need reliable information, not because markup promises placement.
How soon can I claim that a website change worked?
First confirm that the change is live and the affected facts are consistent. Then repeat the documented test after allowing for retrieval freshness. A before-and-after difference alone does not prove causality; preserve comparable prompts and record other changes.
Your next action: run one evidence-led pilot
Choose one category and market, assign an owner, and create the observation worksheet. Test a small prompt set, separate each condition, and correct the highest-impact factual problem. Repeat the same checks and report coverage alongside results. The useful outcome is a defensible account of what happened and what to fix, not a promise of universal AI rankings.
Youssef builds GEOCARA and has run visibility probes across AI engines since 2025. He writes from measured probe data, not speculation.
LinkedIn ↗Related GEO guides
Start your free trial
Audit your site and see how AI engines perceive you.